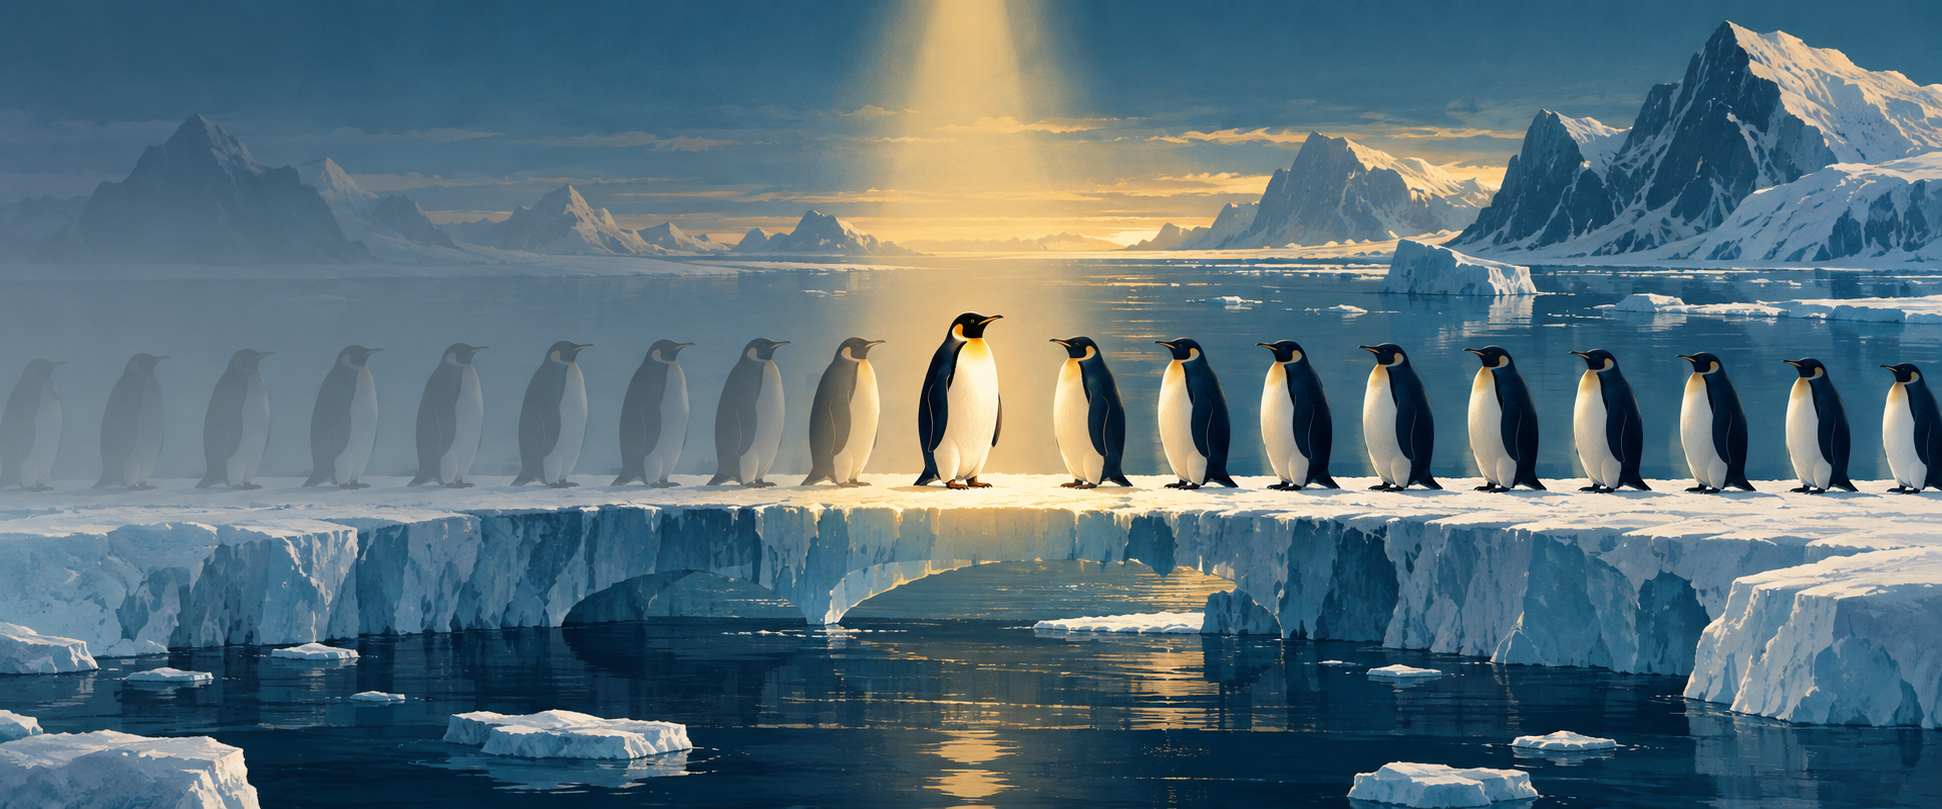
A long line of penguins is a surprisingly good starting point for learning an algorithm. In the Instagram reel linked here, Leandro Hirt | Academify introduces a search that repeatedly narrows an ordered queue. The caption asks how Python could find one penguin among more than a million with only about 20 guesses.
The useful idea is simple: use the order of the data to rule out half the remaining possibilities. The explanation below is our own worked example, not a transcript of the video.
Watch the source reel
Source: Leandro Hirt | Academify — @leandrohirt.oficial on Instagram, dated 6 October 2026 in the platform’s accessible post description. Credit for the reel belongs to its source creator; SLR Journal provides this accompanying explanation and does not claim the video as its own.
The reel’s Portuguese caption describes choosing the middle penguin and discarding half the queue, with the condition that the list is ordered. Instagram controls playback, availability and sign-in requirements. If the embedded player is unavailable, use the original-post link.
Why the middle is useful
Imagine penguins arranged by increasing identification number. If the middle penguin’s number is smaller than the one you want, the target cannot be in the smaller-numbered half. If it is larger, discard the larger-numbered half. If it matches, stop.
This is binary search: repeated comparison with the middle of a sorted range. It stops when it finds a match or no candidates remain. On an array with constant-time index access, the number of search steps grows logarithmically rather than in proportion to the number of items.
Try it with nine numbers
Search for 23 in [2, 5, 8, 12, 16, 23, 38, 56, 72]. This is an original example for this article.
| Check | Middle value | Decision |
|---|---|---|
| 1 | 16 | 23 is larger. Keep 23, 38, 56, 72. |
| 2 | 38 | 23 is smaller. Keep 23. |
| 3 | 23 | Found at index 5, the sixth position. |
For an even-sized range, this implementation chooses the lower of the two middle positions. Other consistent implementations may follow a different comparison path.
What “20 checks” actually means
Repeated doubling gives 2^19 = 524,288 and 2^20 = 1,048,576. For the inclusive-boundary implementation below, one million entries need at most 20 middle-element checks. Exactly 1,048,576 entries can require 21 in the worst case. So “more than a million in 20” can fit some list sizes and search paths, but is not a promise for every larger collection.
A check here means one middle-element probe; the code may evaluate both equality and ordering during that iteration. It does not mean 20 processor instructions or 20 milliseconds. Reading the input, sorting it and displaying the result are separate work.
A Python version you can run
def binary_search(values, target):
    low, high = 0, len(values) - 1
    while low <= high:
        mid = low + (high - low) // 2
        if values[mid] == target:
            return mid
        if values[mid] < target:
            low = mid + 1
        else:
            high = mid - 1
    return -1

print(binary_search([2, 5, 8, 12, 16, 23, 38, 56, 72], 23))
# 5: Python indexes start at zero
low and high mark the remaining range. Moving to mid + 1 or mid - 1 excludes the value already checked, ensuring progress. An empty list immediately returns -1. With duplicate values, this version returns a matching position, not necessarily the first.
The midpoint expression also avoids adding two potentially large indices in fixed-width integer languages, as NIST notes. Python integers do not have that same fixed-width overflow behaviour.
Sorting is the condition, not a free extra
In an unordered line, a small middle value tells you nothing reliable about the values to its left. Binary search must use the same ordering under which the data was sorted. Re-sorting a whole collection for just one lookup may cost more than scanning it once.
Python’s bisect module finds insertion positions in sorted sequences. A returned position is not proof that the target exists: check the boundary and compare the value. Its documentation also distinguishes a logarithmic search from inserting into a list, which can require linear work. Fast lookup does not make every operation fast.
The lesson to remember
The reel supplies a memorable image. The algorithm supplies the reason it works: ordering makes elimination safe. Before using it, ask whether your data is ordered, whether you can access the middle efficiently and what should happen when the value is missing or repeated.
Binary search is not random guessing. Each comparison removes possibilities using information you already have. That is a useful habit well beyond this one example.