A system-design drawing often puts one load balancer in front of several servers. It looks reassuring: if one server stops, requests can reach another. But what happens when the box at the front stops?
The supplied reel asks precisely that question. Adding application servers does not remove a single point of failure in the path to them. The answer depends on whether that box represents one machine, a redundant service or several independently reachable endpoints.
Watch the source reel
Source reel: Ashish Pratap Singh (@ashishps_1), in collaboration with @algomasterio, dated 2026-10-02 in Instagram’s accessible post description. Creator and caption were checked on 8 October 2026. This article is an independently researched explanation of the topic, not a transcript or a claim to ownership of the video.
The embedded reel remains hosted by Instagram. Playback may depend on sign-in, browser settings and the creator’s permissions. Use the original-post link if it is unavailable.
First identify what actually failed
A failed application process, an unreachable load-balancer node, a broken certificate and a bad routing configuration can all look like “the website is down” to a visitor. They require different responses. Start by separating the entry point, the application targets and the dependencies behind those targets.
A healthy front door cannot repair a database outage. Likewise, ten healthy application servers are little help when clients cannot resolve the service name or reach the entry point. Draw the request path and identify which failures each protection actually covers.
Redundancy must include a usable traffic switch
In a self-managed active/standby design, a backup can take over only if a tested mechanism redirects traffic to it. In active/active designs, more than one entry point handles traffic, but there must still be a way to stop sending requests to a failed one.
Two machines sharing the same power supply or faulty configuration can fail together. Place replicas across appropriate failure boundaries, keep their configuration consistent and test the transition. DNS-based switching also depends on client caching; existing connections do not magically migrate to another server.
One managed endpoint need not mean one machine
AWS documents Application Load Balancer nodes in enabled zones. For ordinary Availability Zone deployments, at least two AZ subnets are required. The single service name in your drawing therefore does not imply a single physical appliance. Local Zone and Outpost arrangements have different rules.
That does not make the complete application failure-proof. Targets need sufficient capacity in the surviving location, and your database, authentication and other dependencies need compatible recovery plans.
Also read the actual health-check behaviour: AWS documents ALB fail-open behaviour when all registered targets are unhealthy. “Unhealthy” does not universally mean traffic will stop. A health check is a policy input, not a guarantee that every user operation works.
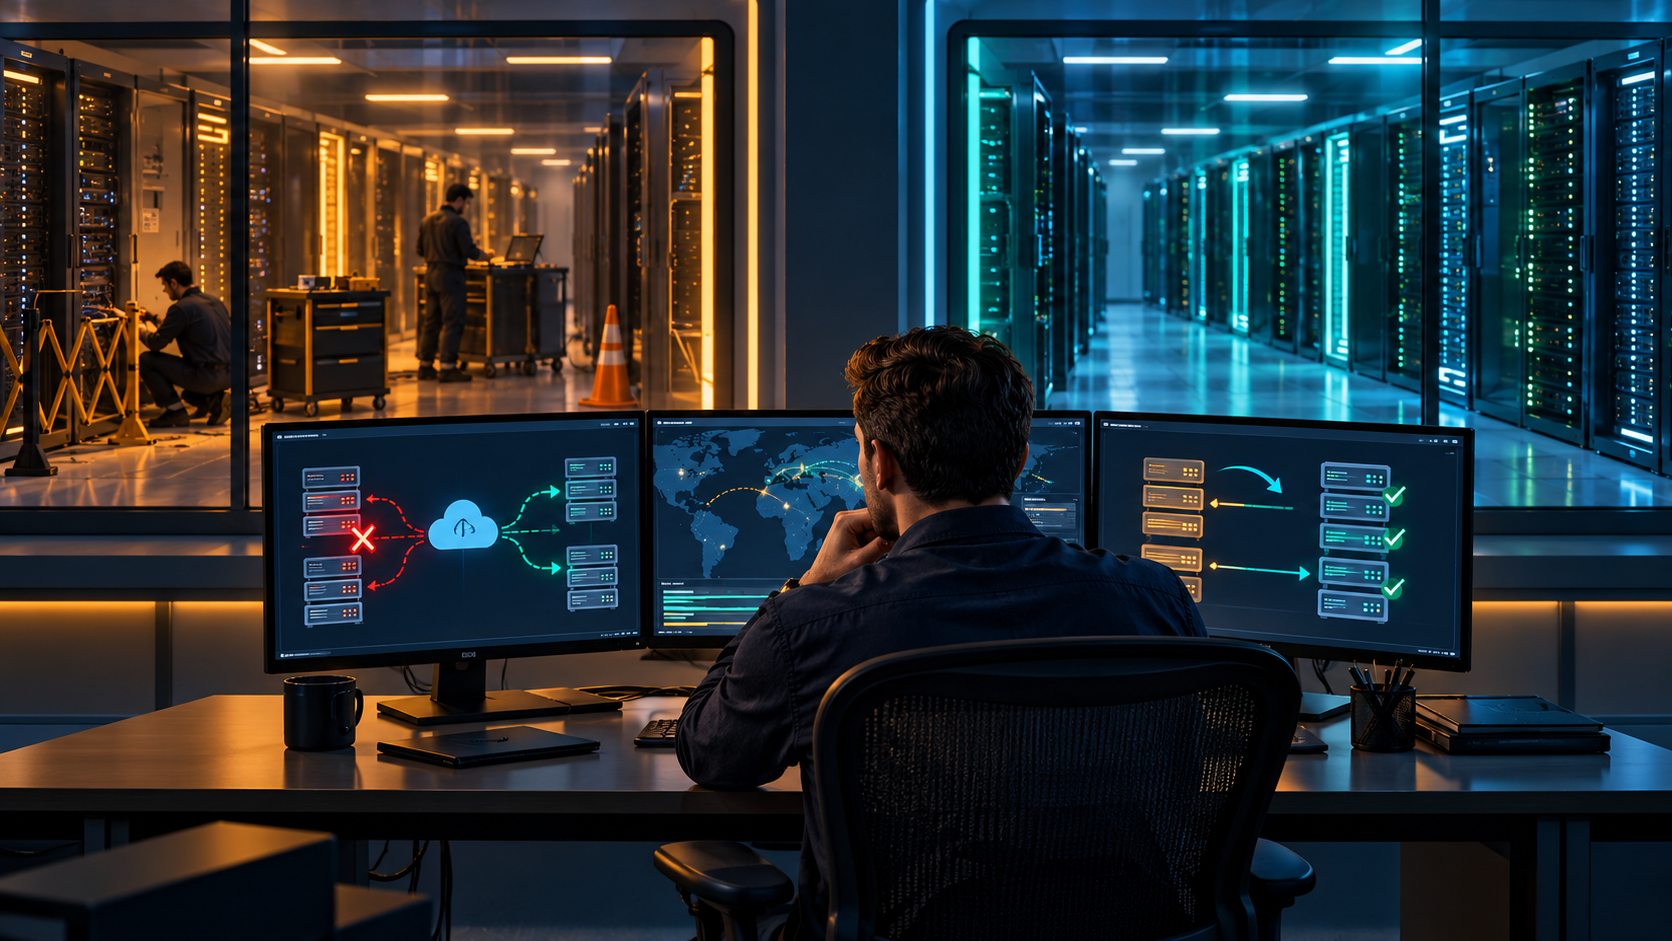
A useful failure drill
- Write down the user operation that must survive, such as reading a product page.
- Disable one target in a controlled test and measure errors and recovery time.
- Test loss of an entry-point or zone using the platform’s supported method.
- Check that the remaining targets can handle the extra load.
- Test a bad deployment and confirm that configuration rollback works.
- Inspect retries: a repeated payment request must not create duplicate charges.
These are design exercises, not instructions to interrupt a production service without preparation. Record what happened to in-flight requests and what users actually saw. An alert that fires after every customer has failed is not sufficient detection.
Match the design to the service
For a small informational site, a managed architecture and a clear recovery procedure may be more appropriate than maintaining a complex pair of proxy servers. A payment service may justify stronger isolation and more demanding recovery targets. Decide using outage impact, operating cost and the team’s ability to maintain the system.
The interview answer is not just “add another load balancer.” Explain failure detection, traffic redirection, remaining capacity and shared dependencies. Reliability comes from a working recovery path, not the number of boxes on the diagram.